Data
See and query the Delta tables in your S3: schema, stats and history from the Delta log, and read-only SQL.
Periplo Cloud · early accessOpen-source coreRuns on your AWS
Periplo brings your lakehouse, pipelines, APIs and AI agents together on your own cloud. Everything it builds and runs stands on loom, our open-source foundation, so it ships with senior practices from day one. Polars by default; Spark when the volume asks for it.
docker run --rm -p 127.0.0.1:8080:8080 ghcr.io/massivedatascope/periplo:latestThe command starts the open-source console on your machine. No sign-up.
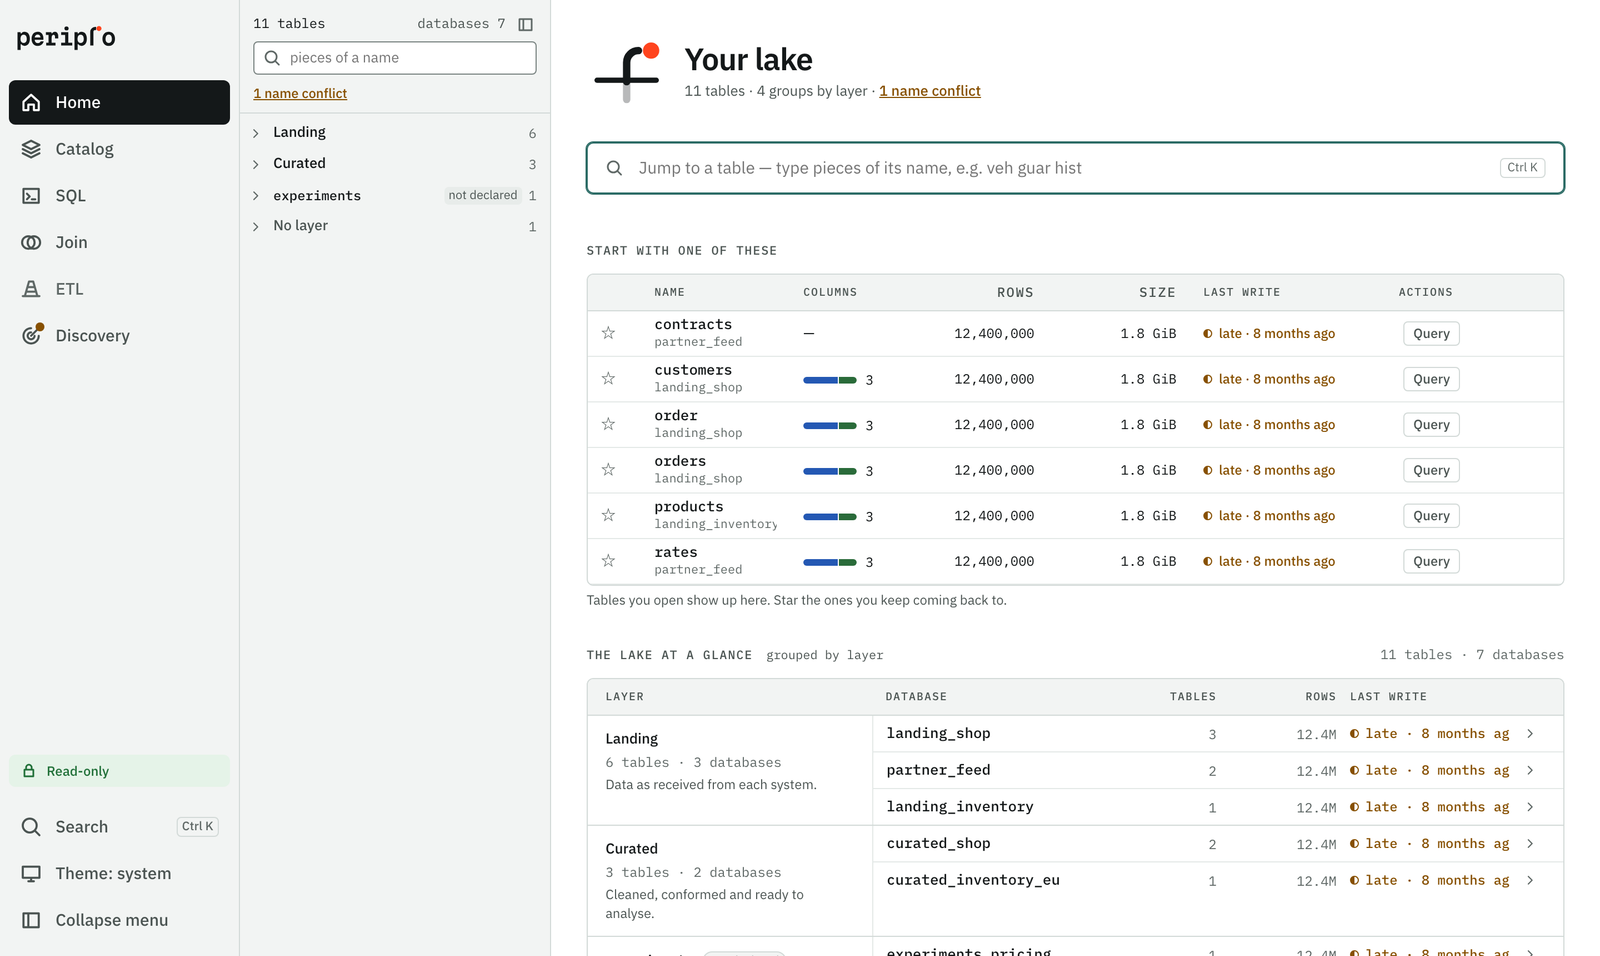
See and query the Delta tables in your S3: schema, stats and history from the Delta log, and read-only SQL.
Sign in with your identity provider, invite members, grant access, keep each client's data apart and audit who accessed what.
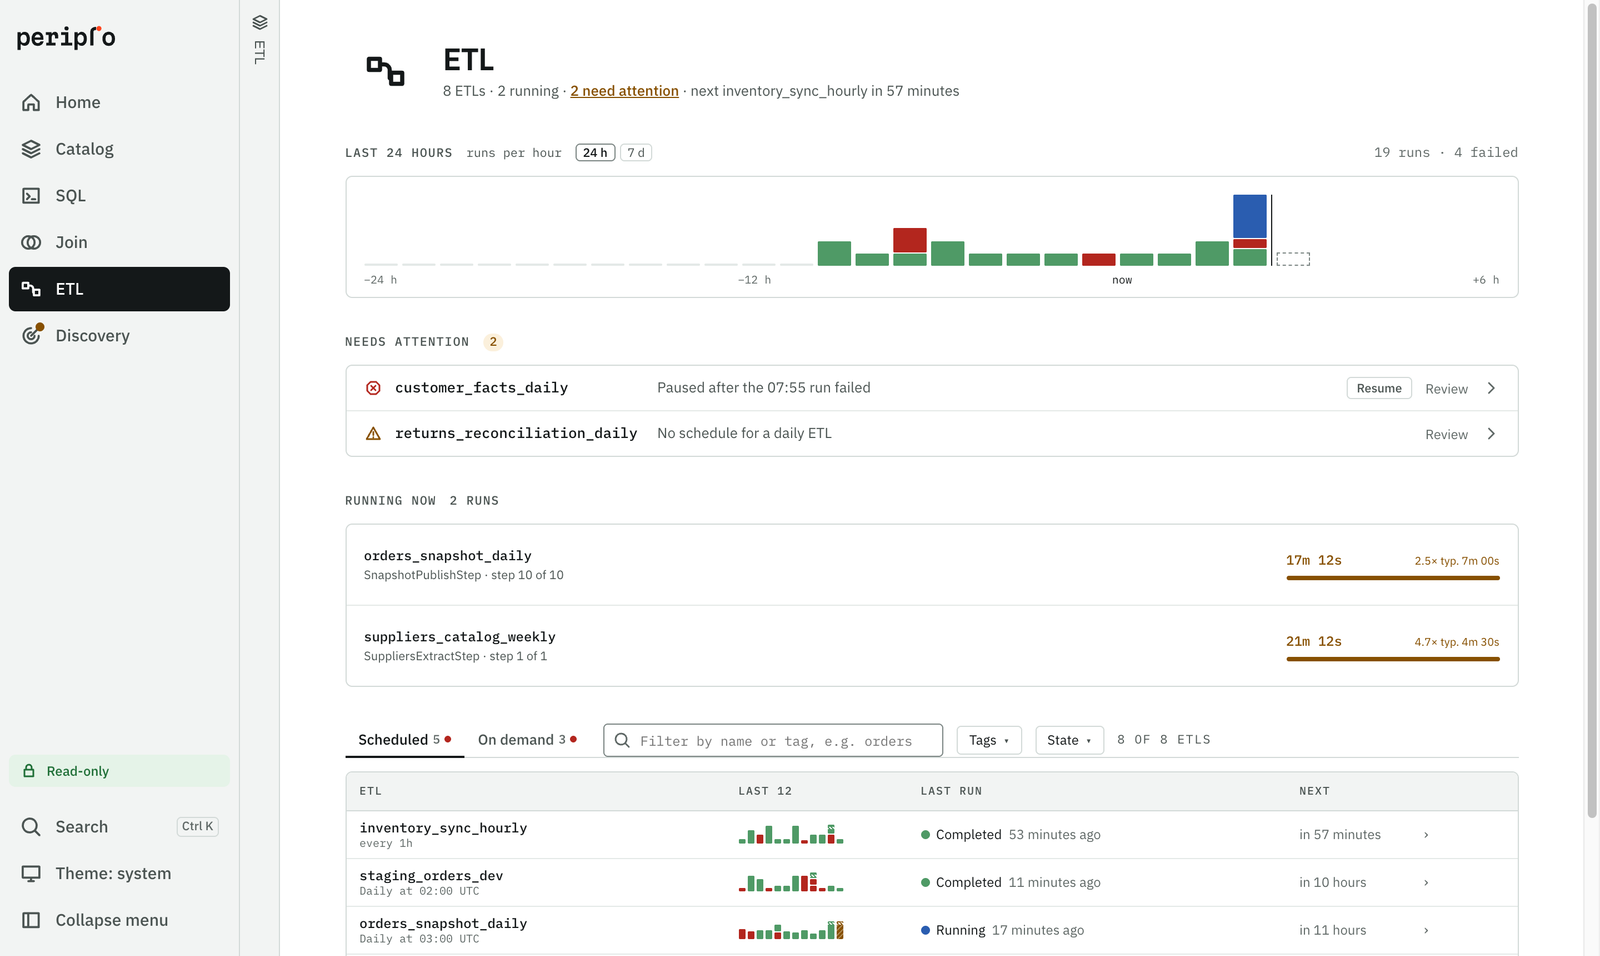
Follow and operate the ETL runs that write your tables, from the same console.
Create a loom project from Periplo, deploy it to your AWS and watch it run in the same console.
An agent that builds with loom's senior patterns, through typed changes you review.
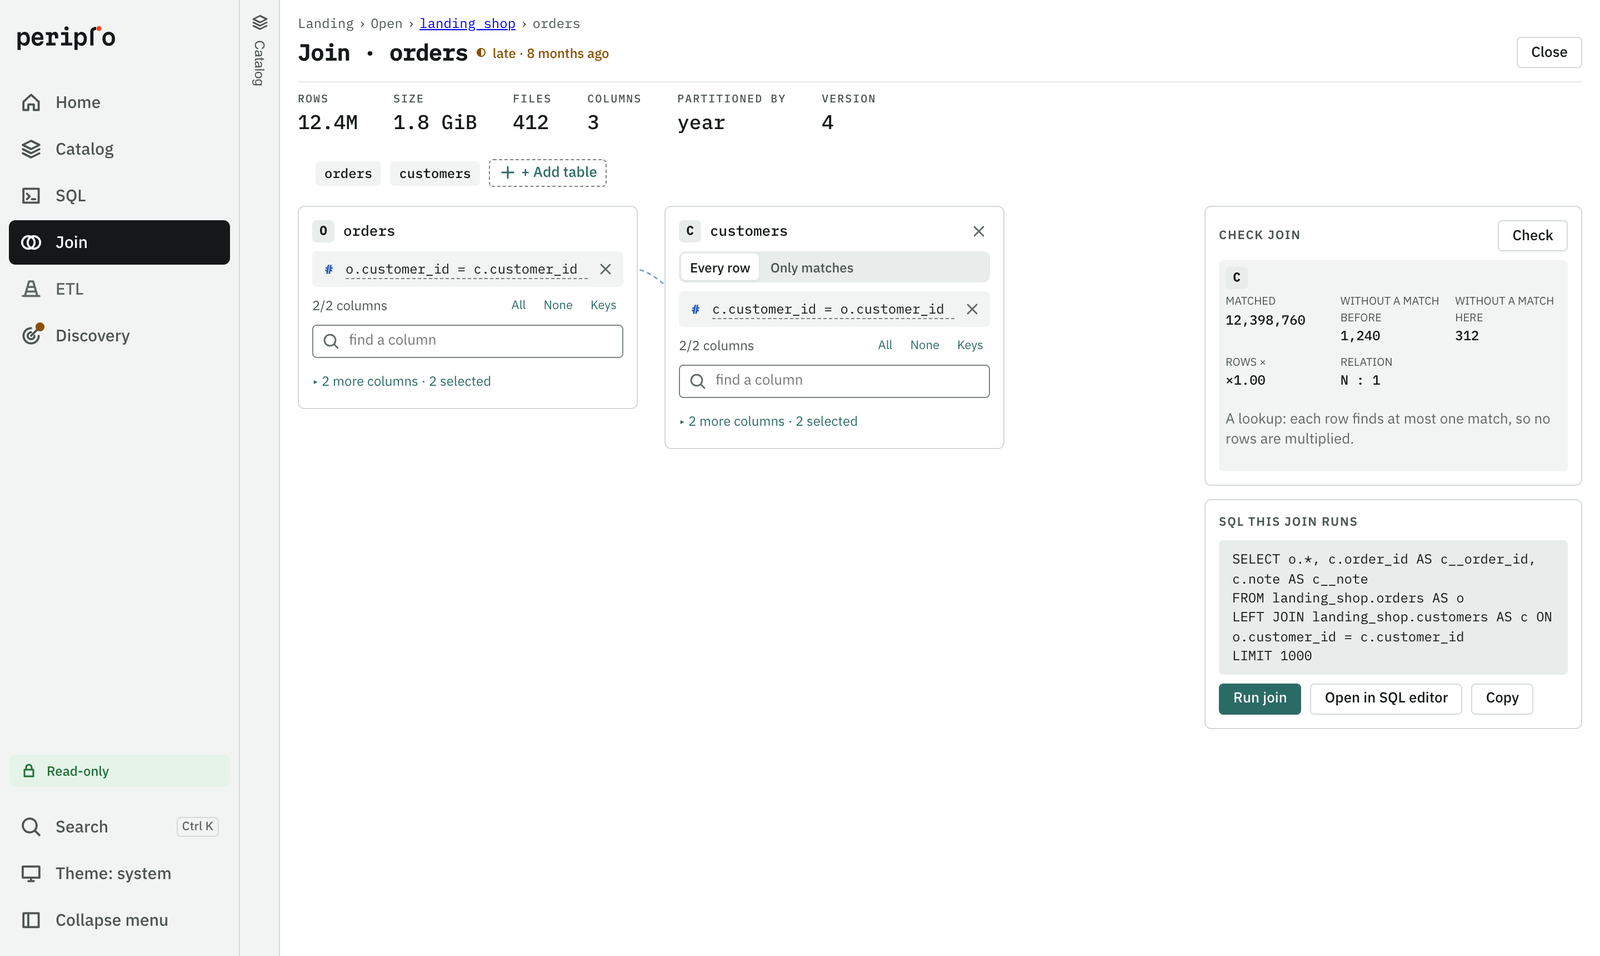
loom is the typed foundation under Periplo: one kernel for APIs, ETL, streaming, agents and jobs. Business rules, contracts and permissions are declared, compiled into a plan and checked before the first request. The same practices, whoever writes the code.
Use it on its own today. Apache-2.0.
pip install loom-kernelclass CreateUserUseCase(UseCase[User, User]): rules = [ Rule.check(F(CreateUser).email, via=_email_must_be_valid), Rule.forbid(lambda _, __, exists: exists, message="email already exists") .from_params("email_exists"), ] async def execute( self, cmd: CreateUser = Input(), email_exists: bool = Exists(User, from_command="email", against="email"), ) -> User: return await self.main_repo.create(cmd)
We sell quality, so we show it. Every figure links to the public source where you can check it.
You declare a pipeline once and choose the engine in configuration. Most data jobs fit on one node and run on Polars for a fraction of the cost; Spark or Databricks take over when the working set outgrows it.
The console and loom, for one engineer on one machine. You run it.
View on GitHub →Your team, your clients and their data, kept apart and audited. We run the control plane; your data stays in your S3. Prepaid, with a spending cap.
Get early accessSenior judgement doesn't scale. So we compile it.
Periplo is made by MassiveDataScope, a software company based in Madrid, Spain. We publish what we build as open source: loom, the Periplo console, plywatch and loom-actions.